The Ultimate Greek Letters Copy-Paste Toolkit: Web, Office, and Mobile Guide
 By Chloe Bennett
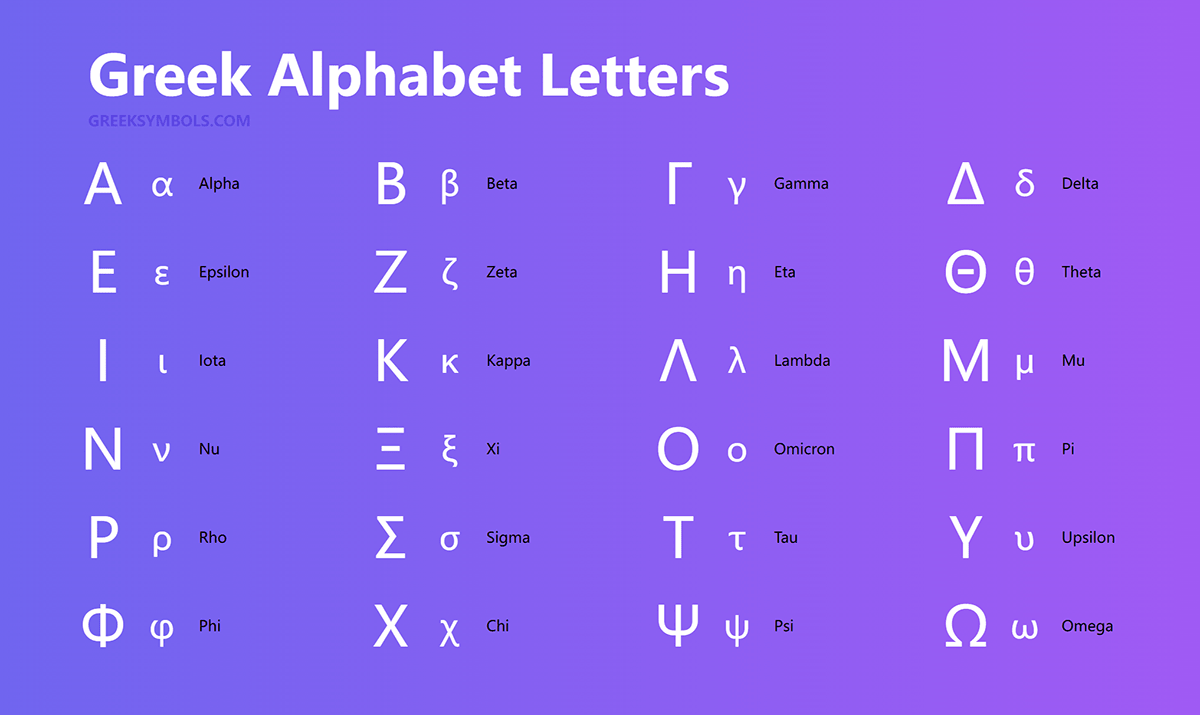
Web development and academic publishing avoid plain copy-pasted characters when raw text might be misinterpreted by source compilers or browser parsers. In these environments, programmatic entity references provide deterministic typography across all rendering engines.
For scientific publishing, standard systems rely on LaTeX math Greek commands. Writing academic manuscripts in Overleaf or local TeX engines requires prefixing the character name with a backslash inside math delimiters. Lowercase commands use full lower strings (such as \sigma, \pi, \omega, and \theta). Uppercase symbols capitalize the first letter (such as \Sigma, \Pi, \Omega, and \Theta).
When compiling research papers, subtle typographic variations matter. Standard LaTeX treats \phi (the curved symbol $\phi$) differently from \varphi (the stroked loop $\varphi$). Similar distinctions exist for \epsilon ($\epsilon$) and \varepsilon ($\varepsilon$). Using the precise command prevents notation errors in published findings.
Front-end web architecture relies on HTML entity names Greek configurations to render cleanly across modern browsers. When raw Unicode presents character encoding risks, developers embed direct entities:
α renders as α
β renders as β
Δ renders as Δ
Σ renders as Σ
ω renders as ω
Ω renders as Ω
While modern UTF-8 document headers handle direct Unicode characters without issue, entity declarations remain standard inside legacy pipelines, database fields, and automated email generation systems.
Chloe Bennett explores the intersection of pop culture, streaming entertainment, digital trends, and contemporary lifestyle. Her weekly commentary reaches thousands of culture enthusiasts.
